Follow-the-moon is still hard

I listened to a podcast this week in which a startup called Emerald AI claimed a revolutionary innovation that allows data centers to throttle energy demand. As I listened to the pod, though, I had a nagging feeling I'd heard this story before. I had, of course. In September 2009 I wrote a short post about what was called "follow the moon" architecture.

The follow-the-moon idea came from researchers at MIT and Carnegie Mellon, who predicted that cloud providers with data centers around the world could route traffic to regions with lower electricity demand and therefore lower costs. Night typically means cooler air and cheaper, off-peak electricity, and the researchers estimated that a strategy like this could cut energy costs by as much as 40%. My question at the time was whether our applications were ready to take advantage of it. Nearly two decades later, we seem not to have advanced very far at all.

A supply-side fix

The October 8, 2026 episode of "This Week in AI" featured Dr. Varun Sivaram, founder of Emerald AI, who described technology that lets a data center throttle its energy use when demand on the grid is high. This approach is a timely response to a high-visibility problem. Data center development is under intense scrutiny right now. When data centers are seen as adding to power grid stress, a solution that can ease demand at the right moments can allow an existing grid to support a data center without a great deal of additional infrastructure build. The throttling happens between the data center and the grid operator, and the customers whose workloads run there rarely see it.

As attractive as this solution seems, I do feel it's a superficial tweak on the margin, and its greatest appeal may be allowing data centers to claim a lower impact on grids and (perhaps) even skip the line versus data centers that don't offer this sort of flexibility.

As I listened to the pod, I couldn't help wondering why consumers of data center-based compute wouldn't be able to steer demand themselves, shifting meaningful amounts of energy usage to low-utilization or low-cost locations.

The missing price signal

What the conversation didn't mention was any way for customers to participate in demand-steering. The 2009 idea assumed someone could see where power was cheap or scarce and move work accordingly. A cloud provider can do that internally, but as far as I can tell, no provider gives customers a price signal that reflects the cost or availability of power in a region. Without one, a customer has no way to steer traffic away from a strained region and no reason to try.

A provider that throttles a facility to relieve the grid is making that decision on behalf of its customers. A price signal would let the customers make the decision themselves, and share in the savings when they do.

Cloud customers already have some control over price. Virtual machines on shared hardware cost less than dedicated hosts because the provider spreads the hardware across many customers. Customers can also choose the regions their workloads run in, but they usually do so to get multi-region backup or to sit closer to their users, not to follow cheaper power.

The solution we'd really need here consists of two parts. First, dynamic pricing would guide usage away from data centers experiencing peak-demand power consumption and toward off-peak locations. Prices could follow a regular schedule based on historic consumption, or they could be fully dynamic, changing minute to minute. The second is the ability to steer a unit of work to a cloud region dynamically in order to take advantage of lower rates.

Latency hasn't changed

In the 2009 post I did some napkin math. The earth is about 25,000 miles around, so even at the speed of light, a data center on the opposite side of the planet is roughly 135 ms away round trip. When I pinged two Australian sites, I got 233 ms and 248 ms, which shows what the routers in between add. The floor is set by physics, so I don't expect today's numbers to look much different.

Follow-the-moon also works against two decades of web performance work. We put static content on CDNs to keep it close to the user. Follow-the-moon asks us to run dynamic processing in whichever region is off-peak, which is often the one farthest from the user. A chatty application, such as a modern UI that fires many small requests as the page updates, is a non-starter for this type of work-steering.

Large units of work for region flexibility

Applications that partition large units of work are ideal for this architecture. Create a self-sufficient unit of work, hand it off and let it run, and connect the pieces with messaging. A message doesn't care that the round trip takes an extra quarter of a second, as long as you know when the work is done. Examples of this sort of work include batch jobs, model training, and analytics: work nobody is waiting on.

Another obvious candidate: since many AI requests take seconds to complete, an extra 150 to 250 ms of network delay is a small share of the total. That makes some AI inference a better candidate for dynamic-region computing than the web applications I was thinking about back in 2009. Training jobs that checkpoint their progress are better candidates still, since they can pause in one region and resume in another.

Space-based data centers

Space-based data centers are born of the same economics. Power availability is the main selling point for launching them, and they're likely to experience some of the same latency issues as a workload looking for off-peak terrestrial power. The workloads that fit orbiting data centers are the same ones: batch and asynchronous work, not low-latency interactive traffic.

Still hard, but solvable

The state of the art today is that supply-side tools are getting better. Techniques like those from Emerald AI can be considered a first step. The two problems I raised in 2009 are still open. Providers haven't given customers a way to see and respond to the price of power, and latency still limits which workloads can move. Until there is a price signal and applications are built to tolerate the delay, the cost savings promised by follow-the-moon architecture will continue to elude us.

Creating expectations in UX

I’ve written previously about the effectiveness and extensibility of Expected and Actual as a mental model to understand usability.  As a reminder, when the actual experience we offer users matches the expected experience they bring to the interaction, the user experiences no friction, and hence, usability is considered good.

In most cases, we accept “expected” where we find it and do our best to match it with “actual”.  This is an important part of usability writings like Don Noman’s “Design of Everyday Things” and Steve Krug’s “Don’t Make Me Think”, which help us understand how users have formed their expectations and how we can map software systems to those expectations.

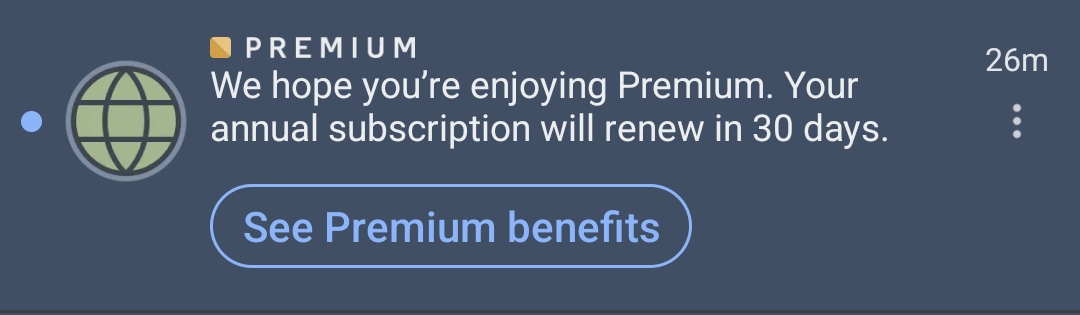
I recently experienced an update from LinkedIn, however, that helped me appreciate how “expected” can be influenced.  On its surface, this update resembles others you may have seen - an email, perhaps, or an SMS you opted into a couple years ago, but this one struck me as just the right amount of notification in just the right place.

An important part of making this work is the channel in which this update is presented.  This update displayed right in the normal LinkedIn updates feed, which made it likely I’d see it, and also made it feel less spammy than a separate notification out of the blue.

It’s also possible that I appreciated this notification more because not a week prior to this, I had a UX experience that felt very different.  My experience began with an alert from my bank.  Had I just authorized a payment of [x] from Amazon?  I didn’t recognize the amount, and checked my Amazon account to see if this corresponded to any recent orders.  It didn’t, so I answered as such to my bank, and they immediately paused my card.  It was late, and I didn’t feel like finding out if my bank had extended hours support, so I decided to deal with it in the morning.  Of course, I forgot about it until lunch, when I reached for my card and remembered it wasn’t going to work.  A call to the bank was next, and the first thing they asked was whether I was a prime member, and might this be a renewal charge.  Sure enough - that was it.  Still no idea why it triggered the bank’s fraud algorithm, but the overall experience from soup to nuts felt crude and disrespectful - especially by comparison to the LinkedIn experience I saw later.

As always, the lesson here is best-applied broadly.  If you have an opportunity to form expectations anywhere in your UX, you’re far more likely to be able to meet them, and met expectations are gold in UX.

Viral adoption, or just creepy?

Earlier this week, I had a very short, very disconcerting Teams meeting.  Shortly after the meeting began, I and the other participant noticed an AI bot show up.  Neither of us were aware we’d invited it, which as you can imagine, was puzzling and more than a little disconcerting to both of us.  Believing discretion is the better part of valor, we both agreed to abandon the meeting, and I did some googling.

It turns out it was my fault (ultimately) the bot showed up in the meeting.  Last week, I’d attended a meeting where one of the hosts had invited this bot to take notes.   Following the meeting, the bot sent a meeting summary to all the attendees (so far, so good).  Having missed a specific point I wanted to look up, I tried accessing the meeting transcript, and was prompted to create an account.

What I hadn’t seen was the (in my opinion) extremely aggressive default behavior on the part of this platform to just go ahead and invite itself to any and all of my future meetings – even those in which I was a guest!

In hindsight, there are at least a couple of lessons to be learned from this experience.  First, as a consumer, all those damned EULAs actually matter.  Choose your connections with care, and consider the permissions you bestow on apps.  It may be a bit inconvenient to pass on an app that seems a bit greedy, but every once in a while, it just may save your bacon.

The other lesson is offered from the perspective of a product designer, and it requires a bit of empathy with respect to your user / audience.  Please consider - realistically - the behaviors your users might actually expect of your product.  In the case of this meeting note-taker, it’s appropriate to have the bot offer its services when I create meetings.  Ideally, I’d have liked to see something interactive the first time the bot has the opportunity to hop on a meeting, and if I elect, “yes”, I think it would be appropriate to ask if I want that to be the behavior for future meetings.  Offer a service to me, but don’t surprise me by joining behind my back!  

I also believe there should have been distinct behaviors for meetings I host vs. meetings I join as a guest.  In my opinion, it would be appropriate for the bot to ask to attend any meeting I join as a guest.  Finally, when joining, the behavior I saw in the meeting was very poorly-sequenced.  When the bot joined my meeting unexpectedly, it hung around for a good 30 seconds before offering anything in the chat window – a definite faux-pas.  I’d expect to immediately see a message indicating who invited the bot and offering actions to stop the recording if desired.  Having this message show up half-a-minute into the meeting is no bueno.

The era of AI is upon us.  Platforms can now do more for us than ever before, and what we’ve seen so far is just the beginning.  However, usability / UX practices need to be engaged for this journey so that these capabilities can be seen as helpful and not subversive or destructive.  Help you expect will always be welcome, but please beware helping in ways that aren’t expected - at best, this will be interpreted as “handling”, and at worst, it’s an unwelcome intrusion.  The first interactions you have with a new customer are precious - don’t botch them and risk losing a customer forever by overstepping your welcome!

Simulating CDC with dbt snapshots

In data modeling, it's common to encounter modeling problems where it's not sufficient to know the data values of an entity right now. You need to be able to know what the values were at a previous point in time. This is most-commonly a data analytics problem, which means this type of model won't be present in native domain tables.

Data changes over time

Let's break down the problem. I'm going to use tables / scenarios from Microsoft's ubiquitous Contoso model. This is fairly well-known, quite generic, and easy to obtain. In fact, if you're interested in downloading data sets in various sizes for these tables (and more), they're available here, and a tool that lets you generate sample data of your own can be found here (might be worth checking this out for generating test data for your own schema, too).

I'm going to focus on some hypothetical changes to the Product table. The Contoso tables are fairly well-engineered for "demo" applications, and the Product table is no different. This is a good baseline for what you'd expect to see in a table like this in a real application. The columns are pretty straightforward, and in this exercise, I'm going to focus on changes that might occur in cost or price over time. Some of these columns are really unlikely to change without resulting in a new sku.

Column NameData type Notes
productkey int4 synthetic key
productcode int4 natural key
productname text
manufacturer text
brand text
color text
weightunit text
weight float8
cost float8 Likely to change over time
price float8 Likely to change over time
categorykey int4
categoryname text
subcategorykey int4
subcategoryname text

In our imaginary data warehouse scenario, we'd like to be able to see changes in columns like cost, price, category, and so on over time. Perhaps we're interested in historic performance of products from different manufacturers, or fill in your own hypothetical, and since these changes over time aren't already present in the source data, we're going to show how to generate these rows using dbt.

In data warehousing, the visibility of changes like this over time is known as a slowly-changing-dimension (SCD), and there are a number of ways to model them. In this example, we're going to show type-2, which creates a new row when changes are detected. In order to do this sort of change detection, you'd need to be able to tell when a row has changed, implying the need for a row ID. Then, each field in the row would have to be compared to see if any of them have changed. Not sophisticated, but unwieldy. Luckily, dbt can do this for us with some simple declarative syntax.

dbt Snapshots

If you're building a data warehouse, there's a good chance you're already using dbt. This open-source tool is available in host-yourself form (dbt core) or as a SAS platform (dbt cloud). The example shown here is built for dbt core, and is available on github. This example uses a dbt seed to load the Contoso Product table - not the way you'd do this at scale, but it makes the demo more portable. Another nod to demo portability - we're using Postgres as our sample data warehouse. All the tools here are fairly agnostic with respect to database, so these techniques adapts to your tool of choice.

The dbt syntax to compute the type-2 SCD is called a snapshot. In our example, we name the output table (producthistory) and the source to be monitored (product). In the config section, note the strategy, which can be either "timestamp" if your source data has a last-updated-date column, or 'check', which evaluates values of columns. Also note the "check_cols" - the value of "all" here is quick and easy, but typically a list of specific columns is preferred for the same reasons we don't use "select *".

snapshots:
  - name: producthistory
    relation: ref('CDC_with_dbt', 'product')
    description:  Slow-changing dimension view of product
    config:
      database: cdcdemo
      strategy: check
      unique_key: ProductKey
      check_cols: all
      hard_deletes: invalidate 

Let's take a look at these snapshots in action. We're going to make changes to the following two rows (shown here in JSON to list fields as rows), and the highlighted columns:

{
"select * from dbt.product where productcode in (0101001, 0101002) \r\n": [
	{
		"productkey" : 1,
		"productcode" : 101001,
		"productname" : "Contoso 512MB MP3 Player E51 Silver",
		"manufacturer" : "Contoso, Ltd",
		"brand" : "Contoso",
		"color" : "Silver",
		"weightunit" : "ounces",
		"weight" : 4.8,
		"cost" : 6.62,
		"price" : 12.99,
		"categorykey" : 1,
		"categoryname" : "Audio",
		"subcategorykey" : 101,
		"subcategoryname" : "MP4&MP3"
	},
	{
		"productkey" : 2,
		"productcode" : 101002,
		"productname" : "Contoso 512MB MP3 Player E51 Blue",
		"manufacturer" : "Contoso, Ltd",
		"brand" : "Contoso",
		"color" : "Blue",
		"weightunit" : "ounces",
		"weight" : 4.1,
		"cost" : 6.62,
		"price" : 12.99,
		"categorykey" : 1,
		"categoryname" : "Audio",
		"subcategorykey" : 101,
		"subcategoryname" : "MP4&MP3"
	}
]}

When we update these fields and run dbt against the updated data, the producthistory table will now show four rows, corresponding to the two original rows and the updated version of each respective row:

{
"select * from dbt.producthistory where productcode in (0101001, 0101002) \r\n": [
	{
		"productkey" : 1,
		"productcode" : 101001,
		"productname" : "Contoso 512MB MP3 Player E51 Silver",
		"manufacturer" : "Contoso, Ltd",
		"brand" : "Contoso",
		"color" : "Silver",
		"weightunit" : "ounces",
		"weight" : 4.8,
		"cost" : 6.62,
		"price" : 12.99,
		"categorykey" : 1,
		"categoryname" : "Audio",
		"subcategorykey" : 101,
		"subcategoryname" : "MP4&MP3",
		"dbt_scd_id" : "daef36db7500c9e531447a11e0e3107a",
		"dbt_updated_at" : "2025-01-17T00:35:19.923Z",
		"dbt_valid_from" : "2025-01-17T00:35:19.923Z",
		"dbt_valid_to" : "2025-01-17T00:37:05.581Z"
	},
	{
		"productkey" : 2,
		"productcode" : 101002,
		"productname" : "Contoso 512MB MP3 Player E51 Blue",
		"manufacturer" : "Contoso, Ltd",
		"brand" : "Contoso",
		"color" : "Blue",
		"weightunit" : "ounces",
		"weight" : 4.1,
		"cost" : 6.62,
		"price" : 12.99,
		"categorykey" : 1,
		"categoryname" : "Audio",
		"subcategorykey" : 101,
		"subcategoryname" : "MP4&MP3",
		"dbt_scd_id" : "4b8654fbe0b5aad13f42ec52524dbe2b",
		"dbt_updated_at" : "2025-01-17T00:35:19.923Z",
		"dbt_valid_from" : "2025-01-17T00:35:19.923Z",
		"dbt_valid_to" : "2025-01-17T00:37:05.581Z"
	},
	{
		"productkey" : 1,
		"productcode" : 101001,
		"productname" : "Contoso 512MB MP3 Player E52 Silver",
		"manufacturer" : "Contoso, Ltd",
		"brand" : "Contoso",
		"color" : "Silver",
		"weightunit" : "ounces",
		"weight" : 4.8,
		"cost" : 6.62,
		"price" : 15.99,
		"categorykey" : 1,
		"categoryname" : "Audio",
		"subcategorykey" : 101,
		"subcategoryname" : "MP4&MP3",
		"dbt_scd_id" : "11d26c8c79e5e304ec85f86913a440b2",
		"dbt_updated_at" : "2025-01-17T00:37:05.581Z",
		"dbt_valid_from" : "2025-01-17T00:37:05.581Z",
		"dbt_valid_to" : null
	},
	{
		"productkey" : 2,
		"productcode" : 101002,
		"productname" : "Contoso 512MB MP3 Player E52 Blue",
		"manufacturer" : "Contoso, Ltd",
		"brand" : "Contoso",
		"color" : "Blue",
		"weightunit" : "ounces",
		"weight" : 4.1,
		"cost" : 6.62,
		"price" : 15.99,
		"categorykey" : 1,
		"categoryname" : "Audio",
		"subcategorykey" : 101,
		"subcategoryname" : "MP4&MP3",
		"dbt_scd_id" : "fd80b5a5d49a315dea7ca9f302065ec7",
		"dbt_updated_at" : "2025-01-17T00:37:05.581Z",
		"dbt_valid_from" : "2025-01-17T00:37:05.581Z",
		"dbt_valid_to" : null
	}
]}

Note the "dbt*" fields added to each record here:

  • dbt_sct_id - a computed unique value based on the primary key and updated-at.
  • dbt_updated_at - this is when dbt last touched this record. In our case, "touch" is alwasys going to be "add".
  • dbt_valid_from - this is the beginng of the effective date window for each record. In the example above, note how dbt_valid_from is set to "now" when the model was initially built. If you need to adjust that value to synthetically backdate initial records to a datetime.min value, you'd need to do this in a subsequent update.
  • dbt_valid_to - this is the end date for the effective date window. Note that for the current record, this value is left null to indicate no expiration date. It won't be set until / unless a new version of that record is created.

Limits of SCD

The example above is an illustration of synthesizing a type-2 SCD records in a worst-case scenario, and as such, it shows some of the pitfalls of this approach. The biggest issue, of course, is that the assignment of effective dates (begin and end) are tied directly to when (and how often) dbt is run. This can lead to some mis-aligned time-based relationships in the warehouse, as shown here:

If your source data happens to have a last-updated date, of course, you can use the "timestamp" strategy in dbt's snapshot configuration, which narrows the window for problems, but won't eliminate it. One of the keys here is to remember that this is a strategy for slowly-changing dimensions - the more active these data sets become, the more susceptible you are to errors.

If you need better accuracy for quickly-changing dimensions, consider modeling relationships in your transactional data. This is something you can see to an extent in the Sales table of the Contoso dataset, where prices and costs of products are saved right in the sales transaction. This captures the attributes that are subject to change in the Product dataset and are also of interest to Sales, reducing the need to link to a specific version of a Product. You can also use a near-realtime CDC tool like Fivetran, which is capable of monitoring source datasets for changes and triggering data events that can feed your warehouse with a much higher fidelity than the solution shown here. Any of these more accurate techniques come with a cost, though, so it's worth keeping this dbt option in your tool box.

ChatGPT-assisted analysis

I was looking through a recording of a web page download in my browser's developer tools the other day, and began ticking off a number of calls to third-party domains. Before you know it, I had opened a document and started counting calls to domains, and it occurred to me -- perhaps ChatGPT could help with this.

So, I opened it up and began asking questions:

Are you able to analyze the page load requests of a web site and summarize calls to third-party web sites (with descriptions of those sites)?

And yes, it turns out, it was able to help. It asked me to upload a HAR file (with instructions about how to generate and save it in developer tools), and began to analyze per my request. I went back and forth a couple times, asking for clarification and tweaks, and after four or five rounds, ChatGPT let me know I'd used up my free analysis allocation.

But then, I noticed a little link the bot had been leaving for me, like a trail of breadcrumbs:

This link popped up a code block that contained the actual analysis for each step:

Going all the way back to the beginning of my chat, grabbing these steps, and dropping into a jupyter notebook, I found they ran almost as-is. Just a couple tweaks to the HAR file load locations were needed to make these scripts work in my local environment.

There are defintitely still adjustments you'd make when investigating specific challenges with / for specific web sites, but this experience demonstrates a few powerful principles:

  1. Use of ChatGPT for analysis. This isn't news to most, but I was quite impressed by the speed with which ChatGPT made progress on this problem. With no code written on my part, ChatGPT made enough progress to help me understand more about my problem quite quickly.
  2. Use of ChatGPT for code generation. Seeing the code generation popping out of the analysis steps without having specifically asked for it -- that was new to me, and a very pleasant surprise. Being fairly new to Python development, it was helpful to see this code as examples of the analysis techniques, including...
  3. Use of HAR traces for website analysis. Seeing this chewed up by the example Python code was a helpful illustration of this technique.

If you're interested in seeing a jupyter notebook illustrating this example, you can find it here:
https://github.com/dlambert-personal/gpt_assisted_har_analysis

UX Lessons from Visual Studio

Commonly, when people think "user experience", they think about screen designs. Apps, web pages, Figma -- all that stuff. The shift from UI design to UX alone is a nod to this practice being more than skin-deep, but I still think a lot of the deeper behavioral aspects of user satisfaction are lost on many -- especially people who have only a casual interest in UI/UX.

I believe there are clues all around us, though, that we can take advantage of if we pay attention. I'll begin with the premise / reminder that real usability is completely invisible. You can only see usability by the absence of impediments to usability. In short, a system is usable when it does exactly what a user expects, even if they can't articulate those expectations.

One of the best examples of invisible usability can be found in Visual Studio, which has been a market-leading IDE for decades now. Built by developers for developers, they've gotten a lot of things right, and even though you're probably not building a tool for use by developers, some of these lessons likely can apply for you, too.

Starting Fresh

Right off the bat, Visual Studio shows its usability by setting users up to be successful when working with a new project. Pick any template you like in Visual Studio, create a new project from it, and it will build successfully. While it might not seem like a big deal, it makes a lot of difference for a new user learning one of these technologies. The ability to start from a solid foundation gives that user confidence to build on that new solution.

What's the lesson? Be aware of the "getting started" experience for your users. Anything you can do to start a user more quickly and with more confidence will help them start using your software with confidence. When users get started with confidence and gain momentum, they're more likely to persevere a bit more if they get stuck later, too.

Save Always

Another subtle way Visual Studio helps is one you probably never gave a second thought. No matter what state your working files are in, you'll never mess one up so badly that Visual Studio won't let you save your work:

A more elegant take on this is to save automatically, so if something goes really wrong, you have a recovered version of your work (which Visual Studio obviously does). Note that automatically saving can actually introduce some small usability hiccups of its own, but that's a problem for another day.

What's the lesson? Document-based applications like Visual Studio and office apps (spreadsheets, docs and the like) typically consider this sort of behavior table stakes these days, and it's not likely you're building one of these, but watch out for behaviors that cause a user to not be able to save work-in-progress. In a UI, you may run into this if you've got a bunch of required fields on a page, and as the field count goes up (and maybe the page count, too), expect that your users' frustration level will go up, too.

It's actually a lot more likely that you'll run into this problem in your APIs. For example, here's a simple method I used in a post about fluent validation:

        public ActionResult CreateDealer(Dealer dealer)
        {
            Guard.Against.AgainstExpression<int>(id => id <= 0, dealer.Id, "Do not supply ID for new entity."); 

            var dvalidator = new DealerValidator();
            var result = dvalidator.Validate(dealer);
            if (result.IsValid)
            {
                _sampleData.Add(dealer);  // SaveChangesAsync() when working with an actual data store
                return CreatedAtAction(nameof(CreateDealer), new { id = dealer.Id }, dealer);
            }
            else
            {
                return BadRequest(result);
            }
        }

While this method effectively validates inputs, the return results to the user aren't especially helpful, and as an object like this scales up in size, it's more likely that a consumer will have partial inputs that don't pass all validation criteria. Rather than preventing this from saving altogether, consider structuring an object like this so that as many values as possible are optional for saving -- even if they're needed in order to have a "valid" object.

In this simple example, we can create a result type that appends a ValidationResult property to the model. We'll return this instead of the "naked" object to show the validation propertied next to the model. The result object is preferrable to embedding a ValidationResult in the model because this keeps the request intact -- there's no reason for the ValidationResult to be part of the CRUD requests.

    public class ModelValidationResult<M, V> where V : AbstractValidator<M>, new()
    {
        public ModelValidationResult(M model)
        {
            this.Model = model; 
        }
        public M Model { get; private set; }
        public FluentValidation.Results.ValidationResult ValidationResult { get; set; }
        public bool Validate()
        {
            V validator = new V();
            this.ValidationResult = validator.Validate(this.Model);
            return ValidationResult.IsValid;
        }
    }

With Validate in the Dealer object, the controller method also becomes a bit simpler:

         public ActionResult CreateDealer(Dealer dealer)
        {
            Guard.Against.AgainstExpression<int>(id => id <= 0, dealer.Id, "Do not supply ID for new entity.");

            ModelValidationResult<Dealer, DealerValidator> res = new ModelValidationResult<Dealer, DealerValidator>(dealer);
            res.Validate();
            _sampleData.Add(dealer);  // SaveChangesAsync() when working with an actual data store
            return CreatedAtAction(nameof(CreateDealer), new { id = dealer.Id }, res);
        }

Note that I left the guard clause in place here -- there will still be some validations that really need to prevent saving bad data, but now that these changes are in place, it's possible to save an object with incomplete data.

This technique won't work in all cases, but consider it if you can support saving objects with a minimal set of data and check for a fully-populated object later.

And more!

If you view Visual Studio with an eye to borrowing UX techniques, you'll see more lessons like these - the Dynamic Validation example I covered earlier is an example. Since you're probably not building an IDE or even a tool for developers, you'll need to interpret some of the techniques liberally, but I assure you the lessons are there. You may also see some negative usability examples -- in fact, sometimes these are easier to see because they get in our way and draw our attention.

If you're interested in source code for this examle, you can find it on Github: https://github.com/dlambert-personal/CarDealer/tree/Guard-vs-validate

Expected and Actual

I'm a fan of simple hooks to summarize complex ideas, and one of my favorite go-to's is simple, memorable and versatile:

Expected == Actual

Not much to look at by itself, but I've gotten a lot of mileage out of this in some useful contexts. You probably recognize one of the most obvious applications immediately: testing / QA. We're well-trained in applying expected == actual in testing, and most bug-reporting contexts will define a bug as a scenario in which actual behavior doesn't match expected behavior.

Even in this simplest application, all the value here is in how we exercise the framework, and I promise if you really work this equation, you'll have a better handle on bugs immediately. Of the two sides of this equation, "expected" usually seems easier, but is almost always more difficult becuase we most of our expectations are unspoken. If I had a dime for every bug report I've seen where "actual" was well-documented but "expected" existed only in the mind of the reporter, for instance, I'd be writing this from a beach in Hawaii.

Of course, that's where the exercise begins to get interesting. "What were you expecting" is a great place to start here. If you can trace expectations to real documented requirements, it's a short conversation (perhaps followed by another conversation to see why that scenario was missed in autometed testing). It's not unheard-of, though for these bugs to occur in scenarios that weren't explicitly called-out in requirements. If this is the case, be sure to examine "expected" to see if it's reasonable for most users to expect the same thing under those conditions, which is a great segue to my next favorite application of expected == actual.

I'm of the opinion that expected == actual is also a pretty good foundation for understanding usability. I touched on this recently in a post about API usability, and it holds true generally, I believe. In that post, I referenced Steve Krug's Don't Make Me Think, which is both an excellent book and another great oversimplification of UX. Both of these are built on the premise that whenever an application does what a user expects it to do, they don't have to think about it, and they consider it usable.

Mountains have been written about how to accomplish this, of course, and I'm not going to improve on the books that talk about those techniques, but as I pointed out with resepct to API usability, consistent behavior goes a long way. Even devices or applications we consider highly usable have a short learning curve, but one a user is invested in that curve, it's tremendously helpful to leverage that learning consistently -- no surprises!

A final consideration that applies in both these areas - when you find a case where "expected" really isn't well-definded yet, and can't be easily-derived based on other use cases (consistency), this is a golden opportunity. Rather than just taking their version of "expected" at face value, ask why they expected that (when possible). You probably won't be able to invest in a full "nine-why's" exercise, but keep that idea in mind. The more you understand about how those expectations formed, the more closesly you can emulate that thinking as you project other requirements.

Besides these examples, where else might you be able to apply "expected vs. actual"?

REST is for nouns

It's hard to believe that REST is over twenty years old now, and although the RESTful style of designing APIs isn't specifically limited to JSON payloads, this style has become associated with transformation from SOAP/XML to a lighter-weight style better-suited to web applications.

The near ubiquity of REST at this point can allow us to slip into some designs that I don't believe are particularly well-suited for this style of API. In this article, I'm going to briefly examine scenarios that work well in a RESTful style -- and why -- and for scenarios that aren't well-suited for REST, we'll look at some alternatives.

A closer look at REST

Most software developers will recognize a RESTful API, but for many, this is a "I'll know it when I see it" recognition. There's no shortage of defintions on the web for REST APIs, and I'd encourage you to browse a few to see what commonalities emerge. Among the most common traits are statelessness, cacheability, and most importantly, a resource-based interface.

The "resource-based interface" is key here - this is the bedrock of the "style" of a RESTful interface. Let's work through a simple example -- say, a car dealer web service. The GET methods here are predictable given a Dealer type:

Here, we've got a list of dealers and a GET for one dealer specified by ID. This is REST at its simplest. The resource here is the Dealer, and much of the fluency of REST comes from being able to predict not only how these APIs will work, but also the remainder of the major operations we'd expect. So, here, GET /Dealer will return a list of all Dealers known to this service, and GET /Dealer/{id} looks for just one.

Without even looking at the API spec, we know what most of the remaining operations should be for Dealers:

  • Add - we expect to be able to add new dealers with a POST and a dealer model.
  • Edit- we expect to POST to /Dealer/{id} with a dealer model to edit that entity.
  • Delete - not all API's will support this, but for if this one does, it would be a DELETE action at /Dealer/{id}.
  • Patch - again, where it's supported, it allows updates by specifying only fields that have changed, and again, we'd expect to find it at /Dealer/{id}.

A big theme contributing to the predictability of REST (which is one of the major appeals) is that you (the designer / developer) determine the resource - Dealer in this case - and the main operations shown here are largely implied. You design the noun, and REST supplies the verbs (they're even commonly referred to as HTTP verbs). Another way to look at these is to consider the resource as an object that's normally at rest (aka REST). Changes to this resource happen only when an HTTP verb acts on the resource.

The tendancy for these resources to change only when impacted by an HTTP verb via this API also contributes to the effectiveness of caching in a RESTful API, as you'll recall from the definitions referenced earlier.

Less universal, but very helpful, in my opinion, for a RESTful interface, is for the resource to behave atomically. Admittedly, the example we're using here is ultra-simplified, but when we act on a Dealer, the closer we can be to these guidelines, the easier it is for API consumers to predict how the API will perform (API's have usability, too!). These guidelines are based on the premise that REST is a web-native design, and developers will expect the API to behave as they'd expect other HTTP resources to behave.

  • Operations are deterministic and cohesive. Ideally, each operation should stand on its own. Domain objects manipulated with these methods will certainly be subject to validation -- as in the url validation shown here. This is a local problem with the specific parameters sent on this call, and most API developers should have no trouble sorting out what they need to do to make this call work.
  • Avoid "bell-ringing". A REST operation should be done when the status is returned to the caller. There will be cases where a changed resource will kick off a workflow, but monitor these carefully. If I kick off a workflow because I changed a resource and I don't care about the workflow, it may still be ok, but watch out for cases where a caller kicks off a workflow that they care about -- this may not be suitable for a simple REST-syntax method.
  • Permissions apply to the whole resource. Imagine that the combination of resource and verb is all the information you've got to determine whether you're authorizing the operation. A user in a given role should ideally be able to create / edit / delete a resource or not.

Complications arise

As API operations become more complex, it's common to see use cases that bend the ideals of those simple REST operations. Many of these nuanced use cases can be shoehorned into a REST-like syntax. This is quite common for simple variations on verbs like Search or modifications or overloads of Add/POST or Edit/PUT. Watch for factors like these - they signal you're moving into API scenarios that require some special attention, and may be clues that you're not really working with RESTful methods anymore:

  • Methods refer to a verb other than normal REST verbs. Some of these (ex: search) can be very compatible with a RESTful syntax and style. If you start running into bespoke verbs, consider switching to an RPC-like call. This can still live in the same API and use JSON for transport -- it's just going to be more verb-forward than noun-forward. These calls are invaluable as your API becomes more complex, but be aware that you give up some of the automatic usability of noun-based REST because these bespoke verbs are unique to your use case and application!
  • Nouns begin to become complex. Consider a trivially-simple car dealer model:
        public int Id { get; set; }
        public string? Name { get; set; }
        public string? Description { get; set; }
        public string? Website {  get; set; }

This ultra-simple model works great in a RESTful API, but it clearly doesn't have enough detail to be useful. As soon as you add more detail / complexity -- in this case, an array of brand affiliations -- the model becomes more difficult to use in the API. This example works great in the domain model, but with the addition of one new BrandAffiliation collection, the JSON structure becomes much more difficult for an API user / developer:

  {
    "id": 3,
    "name": "Capital City Acura",
    "description": "desc",
    "website": null,
    "brandAffiliation": [
      {
        "parent": {
          "name": "Honda",
          "id": 3
        },
        "name": "Acura",
        "id": 1
      }
    ]
  }

A more friendly approach for the API user would likely be a nested REST structure that permits a get or post like /dealer/{dealerid}/parent/{parentid}. If this is starting to look like an OData style, that's great - that's a direction we'll explore more in the future!

Beyond Simple REST

In some cases, complex or complicated scenarios may be better-suited with an RPC-style method. These can live in a predominantly RESTful API - nothing about these is incompatible with the API specifications governing REST, but I think it's helpful to be aware when you're moving away from a pure REST model. Amazon has published a great summary of REST vs. RPC, and it's a great place to start in considering these styles. For our purposes, it's important to recognize that "RPC-like" in style does not imply an actual RPC API!

As use cases evolve beyond that simple REST/OData-like style we looked at earlier, here are some specific places where "simple REST" may not have enough gas in the tank:

  • Verb-centric operations -- APIs where nouns participate, but operations are more about what's happening with those objects. These can be good places to explore those RPC-like calls.
  • Operations tying multiple objects or object types together (likely in a non-heirarchical way). In some cases, graph-ql APIs can fall in this category.
  • Anything that begins to take on state-machine characteristics -- I consider this a special form of verb-centric.
  • Events. Depending on your use case and how deep you're diving into the event pool, these could wind up looking RPC-like or you may be interested in something like Async API.

In all these cases, be sure to be aware of discoverability and predictabilty of your API. In many cases, it can be worth shoehorning an operation into a noun-centric REST call for the sake of consistency. I'll explore some of these nuances in future posts, including places where CQRS meets events and API styles.

In the meantime, try paying attention to nouns & verbs in your API and see if that helps guide some decisions about API style.

APIs have usability, too!

Usability has a long history in software. In fact, as I sat down to pen these words, I googled "history of usability ux" and turned up some scholarly articles going back over 100 years. Too far. In software, you can't go wrong starting with Apple, which puts the origin of UX in the mid 90's. Better.

But for much of this time, we've tuned in to software usability as experienced through our user interfaces by end-users. Today, there's more to usability than user interface design, and I'd like to broaden the discussion a bit.

Usability? What usability?

When you think about great user experiences, typically, we don't consider them to be great user experiences unless we start comparing them to lesser experiences. I believe this is a big clue into how we can apply UX more universally. I really think a lot of usability boils down to doing what a user is expecting you to do... so when you do it, most users will never even notice.

Think about it - when's the last time you gave a passing thought to usability for an application that was already behaving the way you wanted? There are scores of great books on how to achieve usability (I love Steve Krug's Don't Make Me Think, and Don Norman's The Design Of Everyday Things), but I really believe if you can manage to do what the user is expecting you to do, you're typically in pretty good shape.

The changing landscape of applications

Next, let's look at changes in applications and application design. You can probably see where this is going. Whereas once the only users of our applications were end-users operating via a Windows or web interface, cloud-native applications based on microservice architecture rely heavily on APIs to orchestrate, integrate and extend functionality. In many cases, APIs are the interfaces for services, and developers are our users. In this sense, APIs are the interface, and the user experience (UX) is found in the ease-of use of these APIs.

And what is it about an API we'd consider more usable? As with the generalized case above, I think the ultimate yardstick is whether the API behaves the way a developer would expect. I believe the popularity of RESTful APIs, for instance, isn't just because JSON is easy to work with -- it's because a well-written RESTful API is discoverable and predictable.

Note that discoverable isn't the same as documented - even correctly documented, which never happens. Discoverable starts with tools like swagger that expose live documentation of API methods and objects, but it connects with predicatable in an important way: as developers engage with your API and discover how some of it works, consistent behavior and naming creates predicability. When these two factors are combined, they reinforce one another and create an upward spiral for developers in which learning is rewarded and also helps future productivity. And yes - this exact relationship is part of understanding usability in a visual / UX context, as well.

Watch for more posts on API conventions and style soon, and watch for the ways these ideas support one another and ultimately contribute to Krug's tagline: Don't make me think!

A few words on CapEx and OpEx

I initially learned about CapEx and OpEx about five years ago in the sense that I knew they were accounting terms. It's been an ongoing journey for me to learn why they keep coming up in software development. These terms popped up on my radar again recently in a conversation on the excellent ProKanban community slack channel1.

The conversation prompt was an open-ended "what's up with these", and hopped in with some thoughts, summarizing my understanding accrued over the years.

Basic Definitions

First, the easy stuff. These accounting terms do have some good defintions2, and that's a great place to start. Capital Expenditures (note "expenditure" vs. "expense") are considered long-term purchases or investments, wheres Operating Expenses are short-term expenses. The key bits in these definitions are the association of CapEx to an asset account vs. the association of OpEx as an expense.

Although in software development, most of us are used to these terms originating from what we perceive to be the same activity (developing the software), when that time is accounted for, the activity is treated very differently. Let's start with CapEx.

It's important to understand that the accounting definition of CapEx predates its use in tracking software development expenses (also true of OpEx). The original intent or application of CapEx was to account for the purchase of an expensive asset (truck, building, machine) which would then be depreciated over time to reflect its diminishing worth. For software purchased as a one-time license fee, this analogy makes some sense, and starting in the mid 80's, this model was extended to software built in-house. In this scenario, the asset is accrued, or built up in the period prior to "go-live" and then depreciated afterwards. I have several issues with how this relates to modern development practices, but we'll come back to those. In accounting terms, there is an asset that grows as the software is built, and it begins to be tracked as an expense after that go-live event.

In the case of OpEx, the expense and the accounting are considered short-term outlays, tracked against current-period performance. This is a simpler accounting concept, probably more aligned with our experience in development -- we spend time doing a task, and that time is paid for and shows up as an expense in that period. Note that even in the case where CapEx is used to account for the development of a software asset, there will still be expenses associated with running that software, and these costs will be treated as OpEx. A further note on OpEx -- if you've encountered FinOps, note that this field is primarily associated with OpEx.

Accounting deep-dive

For a better understanding of CapEx, I think some examples might be helpful. Forewarned, I'm going to do a T-chart-based deep dive here, so skip ahead if you'd like, but I think if you're in a position where you need to understand why we're tracking CapEx and OpEx, a basic understanding of these concepts is appropriate. I'm also taking some liberties to combine accounts that are likely tracked separately in the interest of simplicity. Let's start with that truck purchase example - a simple cash purchase of a truck (asset) using cash (asset):

Here, we're exchanging one asset for another in a transaction that affects the balance sheet, but does nothing to an income statement. As the truck ages, depreciation is recorded - this reduces the net asset value of the truck (as you'd expect, given age & mileage) and we also record an expense that will show up on the income statement:

Incidentally, just as software incurs OpEx while it's being used, the truck will, too. Not shown in this example are those additional operating expenses like gas, maintenance, and insurance. Pivoting this example to software, we'd expect to see the Capital represented by the software accumulated as an asset during construction. During this period, the increase in assets represents an increase in equity, but this is likely balanced by the expenses occurring in this same period (payroll, contract payments). Once the software is considered operational, the asset begins to incur depreciation as seen with any other hard asset.

Impact of CapEx

So, what's the point of recording software development in this way? First, this method allows financial accounting statements to reflect the intent of the business when development occurs for a while prior to that software providing any real business value. Consider that OpEx is supposed to represent the cost of goods (or services) sold in the current accounting period. If software is built but not being used yet, it's really not fair to count that expenditure against income generated in that period.

I also believe this method of accounting provides an ability to smooth business activities over time -- both the accumulation of the asset value of the software and the discounting of that asset in terms of depreciation occur over a period of time, and both of these streams of accounting entries occur in a fairly predictable way. In a company that's reporting financial results (and especially one that issues guidance about what's expected), this method helps management communicate transactions that are expected with high reliability that the actual transactions that show up on income statements match those expectations. That's important in any company, but vital in a publicly-traded company where surprised are typically punished.

Less clear to me is whether firms take any liberties capitalizing some software vs. others for purposes of steering asset values as these balance sheet and income statement accounts have an impact on measures commonly attributed to company performance3. My understanding of GAAP suggests that an accounting policy shouldn't really vary from one expenditure or project to the next (such that one project is capitalized and the next isn't), but I'd love to hear from practitioners who could walk through particulars.

Flaws in the model

I promised I'd get to some gripes on CapEx and OpEx. Here they are. The elephant in the room, which will surprise nobody in software, is the time and cognitive load involved in tracking time that's supposed to be capitalized separately from time that's not. Best case, if a team or developer can be considered to be only working on CapEx or OpEx-based projects in a given period, frequently, all the time worked in that period can be considered CapEx or OpEx, which reduces reporting overhead. Worst case, you need to ask developers to understand from one task to the next whether that task is considered CapEx-related or OpEx-related. This sort of reporting bugs me no end, because it really detracts from brainpower being brought to bear on building software.

The other big problem I have with the CapEx model for software is the mental model it suggests. In rare cases, software may have been a static one-time expenditure, and accounting for this like it's a filing cabinet or a cement truck may have made sense. In an agile development world, however -- especially one in which we expect to ship an MVP product and add onto it while we operate it -- this model becomes horribly messy, at best, and downright harmful at worst. I strongly suspect that the consensus among developers aligns with the idea that the juice isn't worth the squeeze in this case, but again, I'd love to hear from accountants who could speak to the financial reporting benefits of CapEx for software.


  1. ProKanban community website, twitter/x, and slack links. ↩︎
  2. Some additional good explorations of these terms can be found on Investopedia and Wallstreetprep. ↩︎
  3. These links are good follow-on reading to learn about key accounting kpis and metrics. Growth in assets can also be seen as impacting a comany's future returns. Finally, this thread on Reddit touches on financial reporting and tax implications of these practices. ↩︎